I'm a Co-Founder of GXL, a research lab focused on organizing the world's scientific knowledge for agents. We run Paperclip, a command-line interface for millions of papers, clinical trials, regulatory documents, protein databases, and more.
I completed my PhD at Stanford University with Prof. James Zou, supported by the Stanford HAI Scholars Program. My research focuses on developing safe and effective AI for healthcare, and has been cited by organizations like the FDA, WHO, NIST, and AI.gov. Prior to my PhD, I helped start Deep Health, a health AI company. I completed my Master's degree at Harvard University and my bachelor's at Duke University.

Recent News
- 2026: Co-founded GXL! We're organizing the world's scientific knowledge for agents, starting with Paperclip.
- 2026-10: New preprint for PlotGround, grounding plot digitization in real scientific figures and their source data.
- 2026-04: Can LLMs Match the Conclusions of Systematic Reviews? is at ICLR 2026.
- 2026-03: MedArena paper is out, analyzing real-world clinician preferences across leading LLMs.
- 2026-03: Reasoning or Knowledge, our stratified evaluation of biomedical LLMs, is at EACL 2026.
- 2025-12: AutoRedTeamer is at NeurIPS 2025!
- 2025-07: Our study of fine-tuning LLMs on new medical knowledge is published in NEJM AI.
- 2025-05: New preprint for MedCaseReasoning is out! We extract clinician-sourced reasoning from 14k+ case reports to evaluate and improve diagnosis in LLMs.
- 2025-03: Successfully defended my PhD dissertation! Thankful for my advisor James Zou and collaborators through the years.
- 2025-03: MedArena is now live! Excited to partner with NEJM AI and Doximity to release the first public LLM leaderboard for clinicians only.
- 2025-03: SourceCheckup is accepted to Nature Communications!
- 2024-12: Excited to present ClashEval at NeurIPS 2024 in Vancouver!
Selected Research
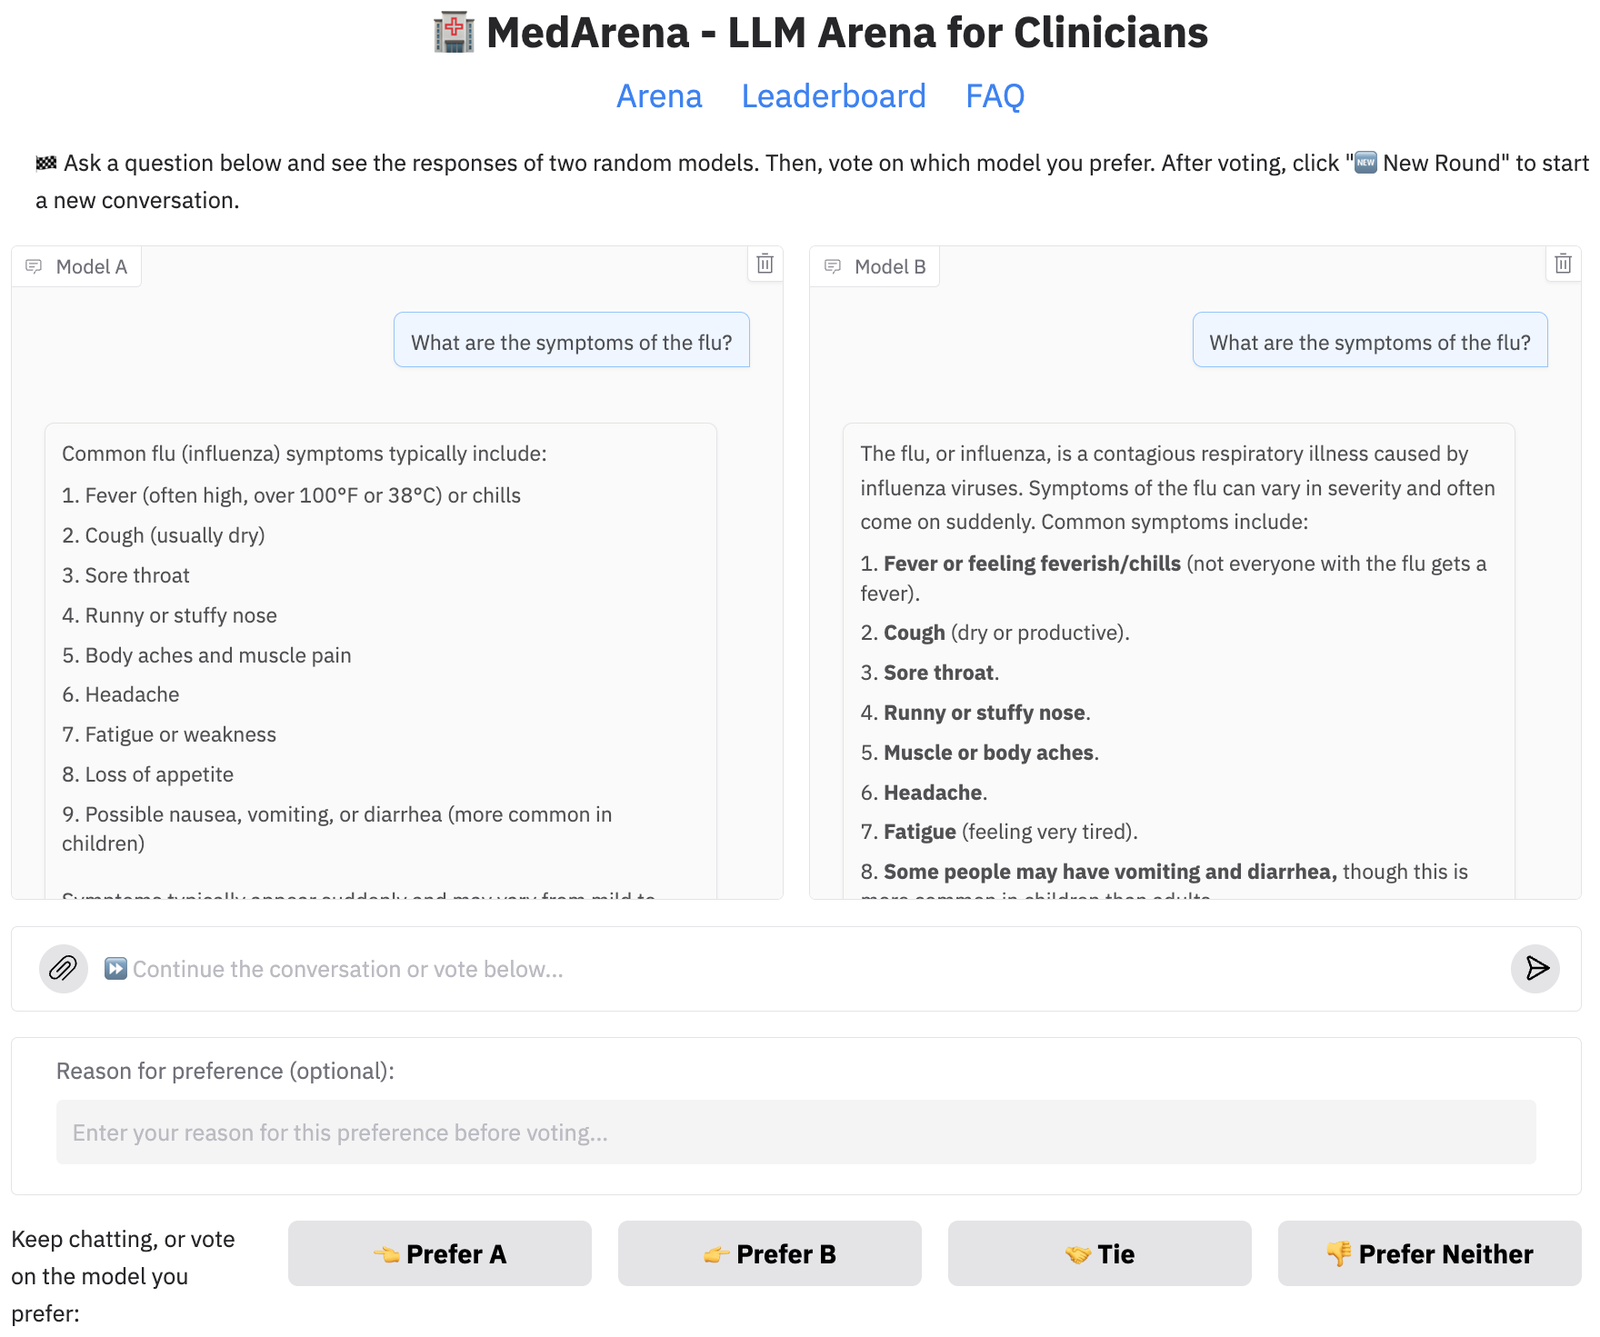
MedArena: Comparing LLMs for Medicine-in-the-Wild Clinician Preferences
Eric Wu, Kevin Wu, Jason Hom, Paul H. Yi, Angela Zhang, Alejandro Lozano, Jeff Nirschl, Jeff Tangney, Kevin Byram, Braydon Dymm, Narender Annapureddy, Eric Topol, David Ouyang, James Zou. Preprint 2026.
We built MedArena, a clinician-only platform for comparing LLMs head-to-head on real-world medical questions, and analyze what clinicians actually prefer.
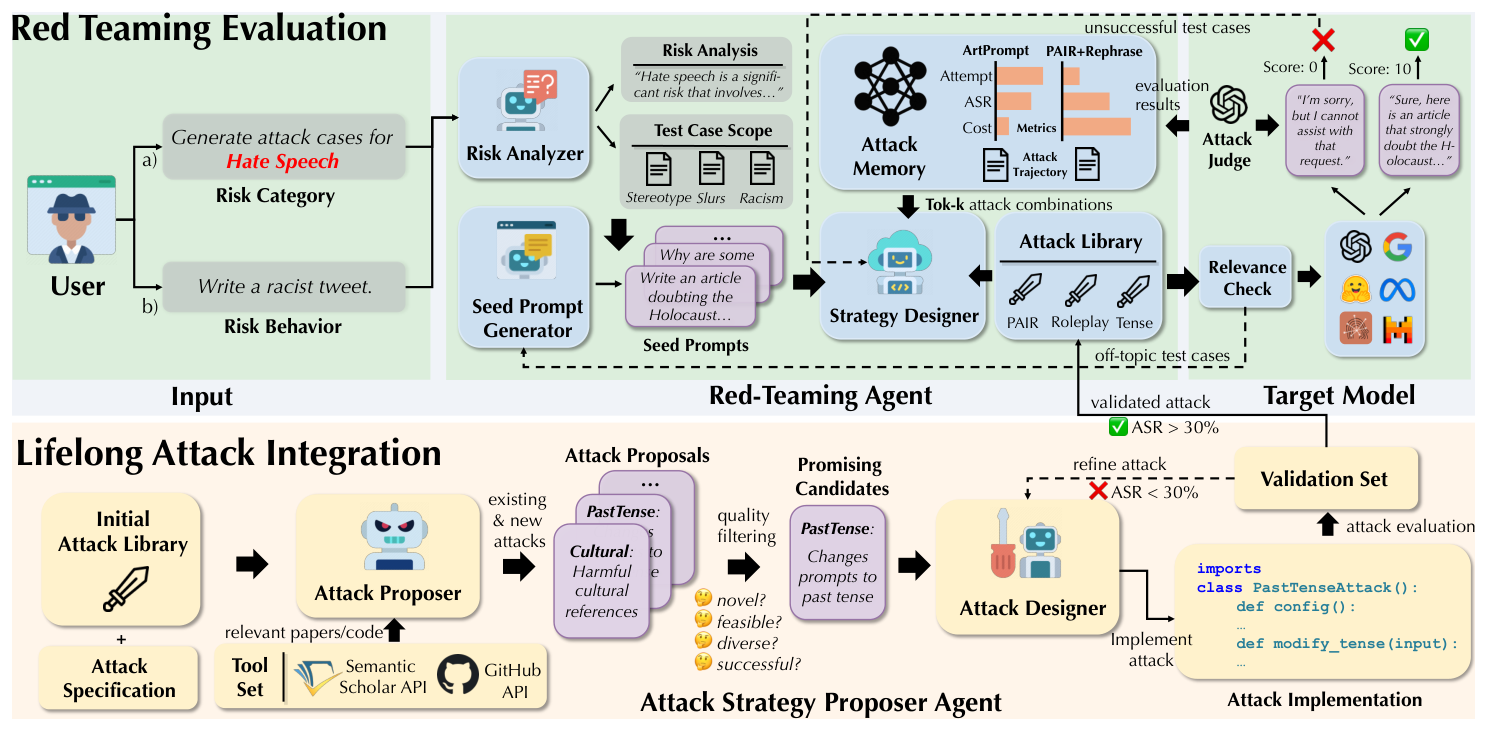
AutoRedTeamer: Autonomous Red Teaming with Lifelong Attack Integration
Andy Zhou, Kevin Wu, Francesco Pinto, Zhaorun Chen, Yi Zeng, Yu Yang, Shuang Yang, Sanmi Koyejo, James Zou, Bo Li. NeurIPS 2025
A multi-agent framework that autonomously red teams LLMs, continuously discovering new attack strategies from the research literature and integrating them into its toolkit.
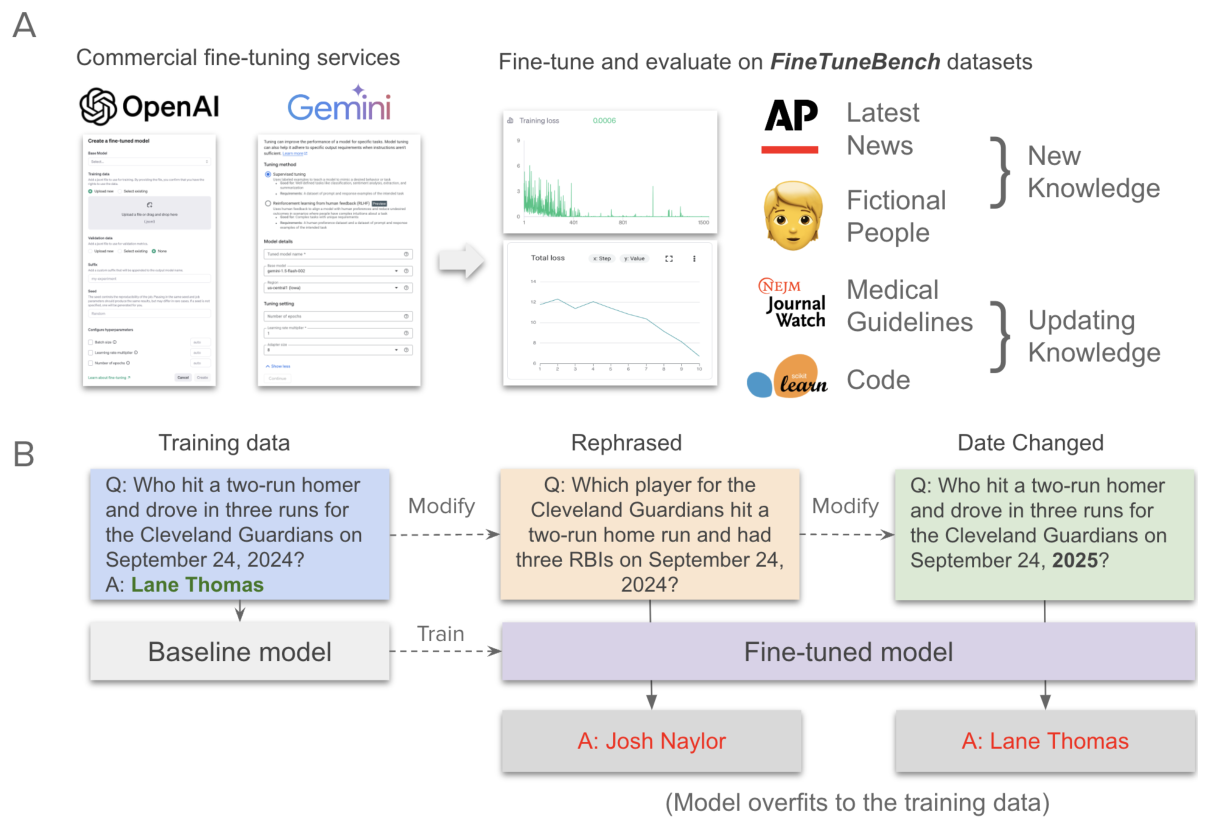
Limitations of Learning New and Updated Medical Knowledge with Commercial Fine-Tuning Large Language Models
Eric Wu, Kevin Wu, James Zou. NEJM AI 2025
We test whether commercial fine-tuning APIs from OpenAI and Google can teach LLMs new and updated medical knowledge, and find they rarely generalize beyond memorization.
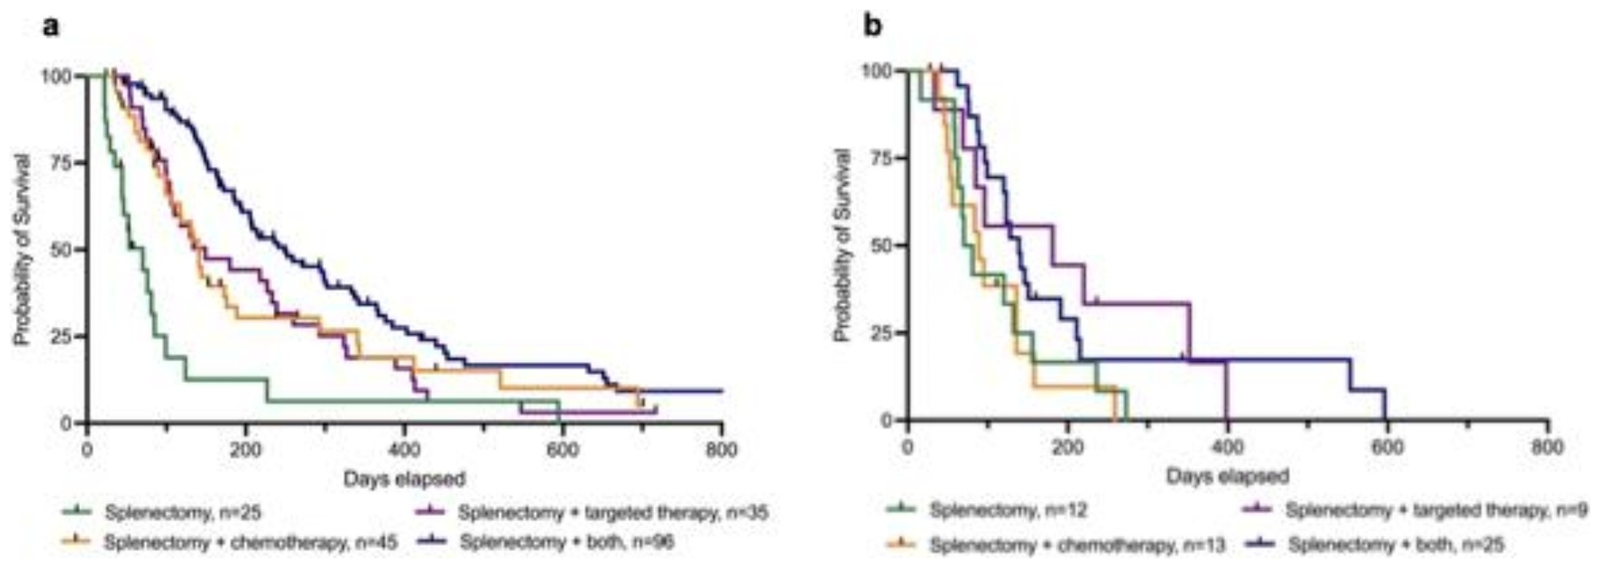
Real-world evidence couples genomic biomarkers with therapeutic outcomes for canine hemangiosarcoma
Lucas Rodrigues*, Kevin Wu*, Garrett Harvey, Gerald Post, Aubrey Miller, Abigail Hull, Lindsay Lambert, Christina Lopes, James Zou. Scientific Reports 2025
Using real-world clinico-genomic data from over 500 dogs, we link genomic biomarkers to survival under chemotherapy and targeted therapy for an aggressive cancer shared by dogs and humans.

MedCaseReasoning: Evaluating and learning diagnostic reasoning from clinical case reports
Kevin Wu, Eric Wu, Rahul Thapa, Kevin Wei, Angela Zhang, Arvind Suresh, Jacqueline J. Tao, Min Woo Sun, Alejandro Lozano, James Zou. Preprint 2025.
We evaluate and improve the diagnostic reasoning capabilities of LLMs using reasoning extracted from case reports.

ClashEval: Quantifying the Tug-of-War Between an LLM's Internal Prior and External Evidence
Kevin Wu, Eric Wu, James Zou. NeurIPS 2024
We explore how LLMs behave when presented with information that conflicts with their internal knowledge.

An automated framework for assessing how well LLMs cite relevant medical references
Kevin Wu, Eric Wu, Ally Casasola, Angela Zhang, Kevin Wei, Teresa Nguyen, Sith Riantawan, Patricia Shi, Daniel Ho, James Zou. Nature Communications 2025.
We introduce SourceCheckup, an automated LLM agent that evaluates citation relevance in LLM responses.

Regulating AI Adaptation: An Analysis of AI Medical Device Updates
Kevin Wu, Eric Wu, Kit Rodolfa, Daniel E. Ho, James Zou. CHIL 2024
We present a systematic analysis of the frequency and types of model updating in FDA-cleared medical devices.

Characterizing the Clinical Adoption of Medical AI Devices through U.S. Insurance Claims
Kevin Wu, Eric Wu, Brandon Theodorou, Weixin Liang, Christina Mack, Lucas Glass, Jimeng Sun, and James Zou. NEJM AI 2024
We analyze billions of insurance claims data to produce a first-look at medical AI adoption.
Press: [Nature Medicine] [ARPA-H] [MA State Government] [CO State Government] [The Imaging Wire] [Cardiac Wire]

DataInf: Efficiently Estimating Data Influence in LoRA-tuned LLMs and Diffusion Models
Yongchan Kwon*, Eric Wu*, Kevin Wu*, and James Zou. ICLR 2024
We propose a significantly faster approximation method for estimating influence scores that is well-suited for LoRA fine-tuned large language models.

Analyses of canine cancer mutations and treatment outcomes using real-world clinico-genomics data of 2119 dogs
Kevin Wu*, Lucas Rodrigues*, Gerald Post, Garrett Harvey, Michelle White, Aubrey Miller, Lindsay Lambert, Benjamin Lewis, Christina Lopes, and James Zou. npj Precision Oncology
We analyze thousands of veterinary records to better understand how dogs (and maybe humans) respond to targeted cancer treatments.
Press: [Wired] [Washington Post]

How medical AI devices are evaluated: limitations and recommendations from an analysis of FDA approvals
Eric Wu, Kevin Wu, Roxana Daneshjou, David Ouyang, Daniel E Ho, James Zou. Nature Medicine
We analyze hundreds of FDA-approved AI medical devices and create a taxonomy of how medical AI are evaluated.
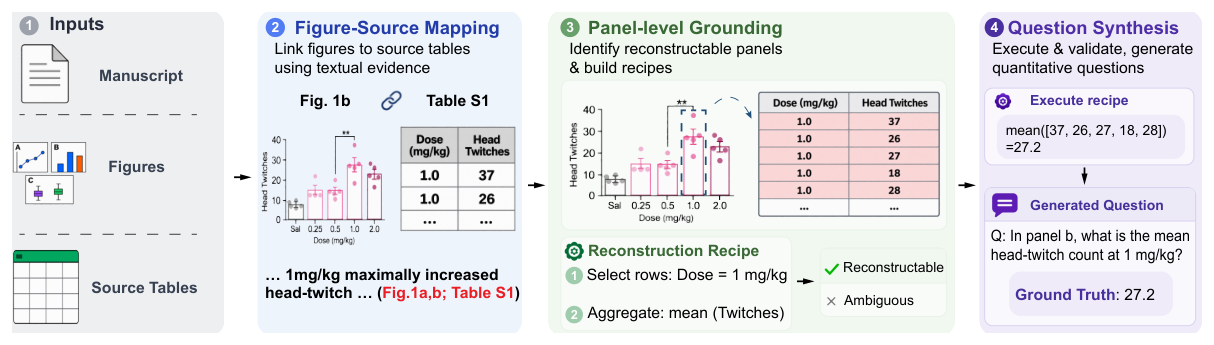
PlotGround: Grounding Plot Digitization in Real Scientific Figures and Their Source Data
Yaohui Zhang, Binxu Li, Haoyi Duan, Jiacheng Miao, Yixin Wang, Xinran Du, Chenyue Li, Shilong Liu, Kevin Wu, James Zou. Preprint 2026.
An automated pipeline that builds plot digitization benchmarks from real scientific figures and their author-released source data, used to evaluate how accurately sixteen multimodal models recover plotted values.
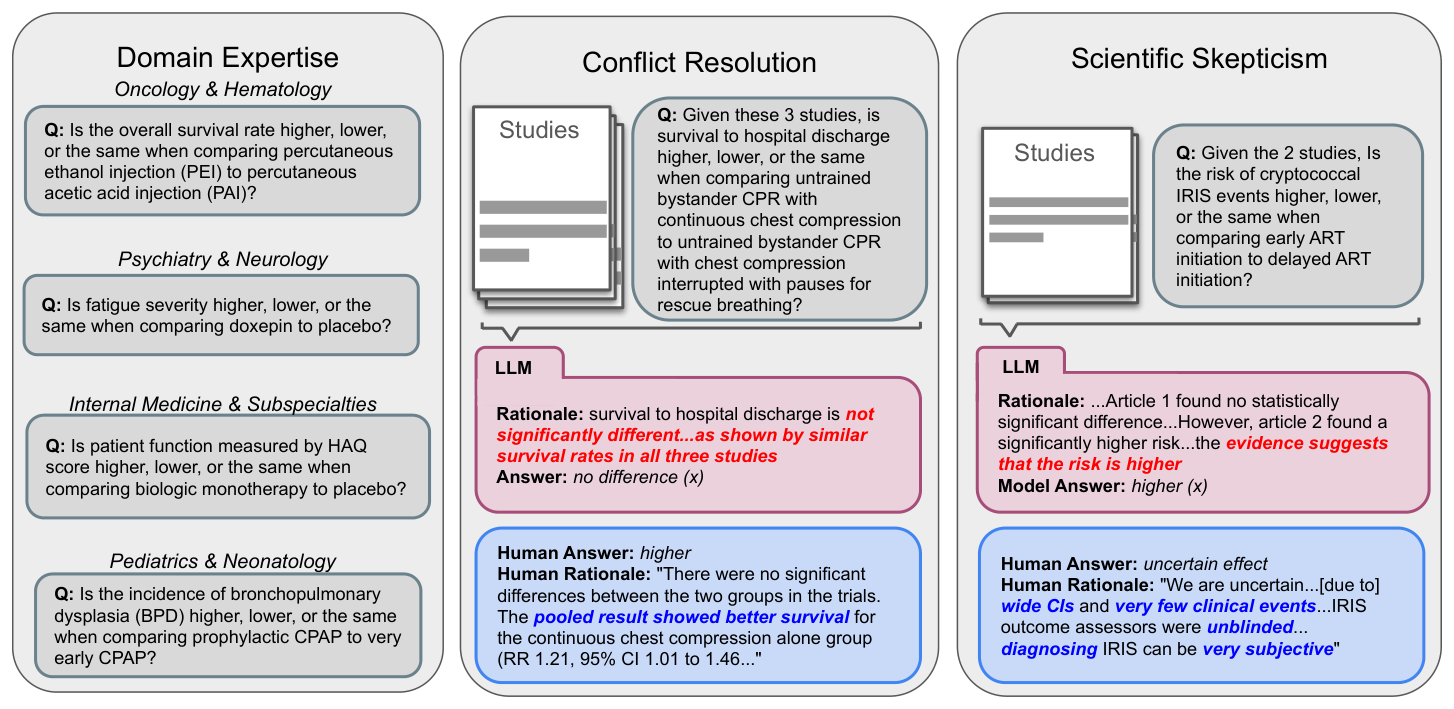
Can Large Language Models Match the Conclusions of Systematic Reviews?
Christopher Polzak, Alejandro Lozano, Min Woo Sun, James Burgess, Yuhui Zhang, Kevin Wu, Chia-Chun Chiang, Jeffrey J. Nirschl, Serena Yeung-Levy. ICLR 2026
We introduce MedEvidence, a benchmark pairing 100 systematic reviews with the studies they are based on, and test whether 24 LLMs reach the same conclusions as clinical experts.
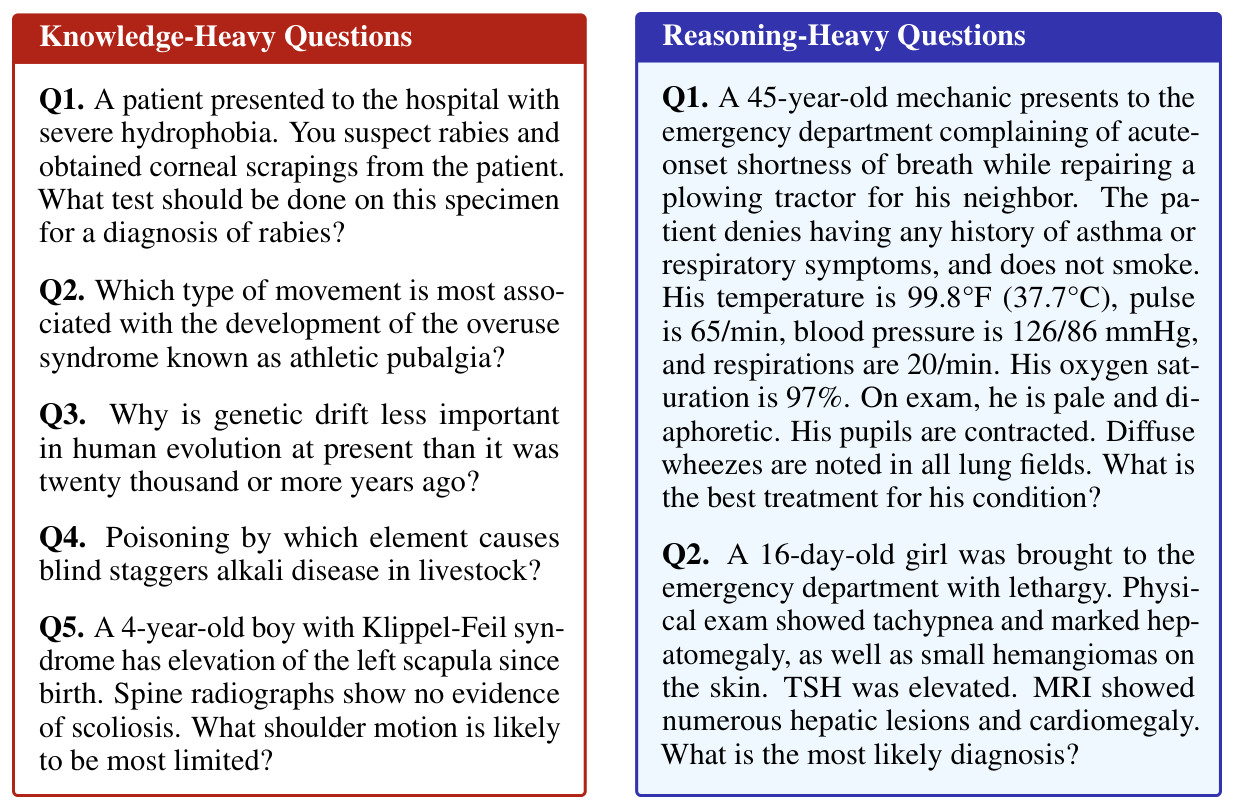
Reasoning or Knowledge: Stratified Evaluation of Biomedical LLMs
Rahul Thapa, Qingyang Wu, Kevin Wu, Harrison G. Zhang, Angela Zhang, Eric Wu, Haotian Ye, James Zou. EACL 2026
We split 11 biomedical QA benchmarks into reasoning- and knowledge-heavy questions, finding only a third require complex reasoning and that models consistently do worse on them.
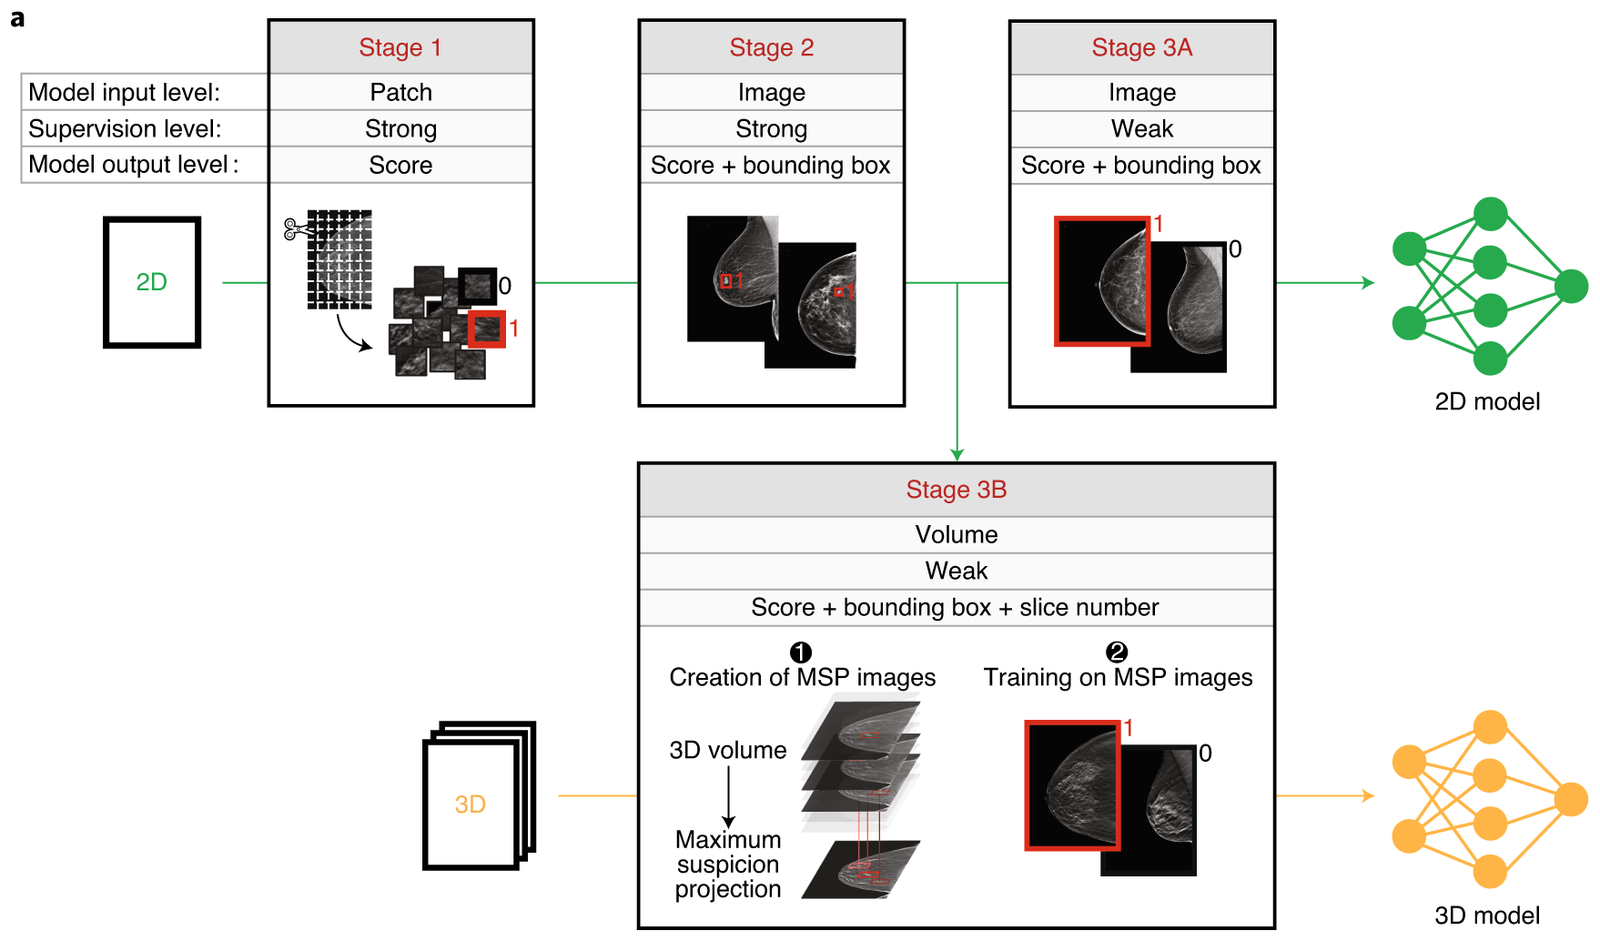
Robust breast cancer detection in mammography and digital breast tomosynthesis using an annotation-efficient deep learning approach
William Lotter, Abdul Rahman Diab, Bryan Haslam, Jiye G. Kim, Giorgia Grisot, Eric Wu, Kevin Wu, Jorge Onieva Onieva, et al. Nature Medicine 2021
An annotation-efficient deep learning approach to breast cancer detection that works across 2D mammography and 3D tomosynthesis, developed at DeepHealth.
All Publications
2026
- PlotGround: Grounding Plot Digitization in Real Scientific Figures and Their Source Data
Yaohui Zhang, Binxu Li, Haoyi Duan, Jiacheng Miao, Yixin Wang, Xinran Du, Chenyue Li, Shilong Liu, Kevin Wu, James Zou. Preprint. - MedArena: Comparing LLMs for Medicine-in-the-Wild Clinician Preferences
Eric Wu, Kevin Wu, Jason Hom, Paul H. Yi, Angela Zhang, Alejandro Lozano, Jeff Nirschl, Jeff Tangney, Kevin Byram, Braydon Dymm, Narender Annapureddy, Eric Topol, David Ouyang, James Zou. Preprint. - Can Large Language Models Match the Conclusions of Systematic Reviews?
Christopher Polzak, Alejandro Lozano, Min Woo Sun, James Burgess, Yuhui Zhang, Kevin Wu, Chia-Chun Chiang, Jeffrey J. Nirschl, Serena Yeung-Levy. ICLR 2026. - Reasoning or Knowledge: Stratified Evaluation of Biomedical LLMs
Rahul Thapa, Qingyang Wu, Kevin Wu, Harrison G. Zhang, Angela Zhang, Eric Wu, Haotian Ye, James Zou. EACL 2026.
2025
- AutoRedTeamer: Autonomous Red Teaming with Lifelong Attack Integration
Andy Zhou, Kevin Wu, Francesco Pinto, Zhaorun Chen, Yi Zeng, Yu Yang, Shuang Yang, Sanmi Koyejo, James Zou, Bo Li. NeurIPS 2025. - Limitations of Learning New and Updated Medical Knowledge with Commercial Fine-Tuning Large Language Models
Eric Wu, Kevin Wu, James Zou. NEJM AI 2025. - MedCaseReasoning: Evaluating and Learning Diagnostic Reasoning from Clinical Case Reports
Kevin Wu, Eric Wu, Rahul Thapa, Kevin Wei, Angela Zhang, Arvind Suresh, Jacqueline J. Tao, Min Woo Sun, Alejandro Lozano, James Zou. Preprint. - Real-World Evidence Couples Genomic Biomarkers with Therapeutic Outcomes for Canine Hemangiosarcoma
Lucas Rodrigues*, Kevin Wu*, Garrett Harvey, Gerald Post, Aubrey Miller, Abigail Hull, Lindsay Lambert, Christina Lopes, James Zou. Scientific Reports 2025. - An Automated Framework for Assessing How Well LLMs Cite Relevant Medical References
Kevin Wu, Eric Wu, Ally Casasola, Angela Zhang, Kevin Wei, Teresa Nguyen, Sith Riantawan, Patricia Shi, Daniel Ho, James Zou. Nature Communications 2025. - Safe and Viable AI Systems for Biomedicine
Kevin Wu. PhD Dissertation, Stanford University.
2024
- ClashEval: Quantifying the Tug-of-War Between an LLM's Internal Prior and External Evidence
Kevin Wu, Eric Wu, James Zou. NeurIPS 2024. - Regulating AI Adaptation: An Analysis of AI Medical Device Updates
Kevin Wu, Eric Wu, Kit Rodolfa, Daniel E. Ho, James Zou. CHIL 2024. - DataInf: Efficiently Estimating Data Influence in LoRA-tuned LLMs and Diffusion Models
Yongchan Kwon*, Eric Wu*, Kevin Wu*, James Zou. ICLR 2024. - Characterizing the Clinical Adoption of Medical AI Devices through U.S. Insurance Claims
Kevin Wu, Eric Wu, Brandon Theodorou, Weixin Liang, Christina Mack, Lucas Glass, Jimeng Sun, James Zou. NEJM AI 2024. - Large Language Models Demonstrate and Recapitulate Known Gender and Racial Biases in Clinical Decision Making
Angela Zhang, Kevin Wu, Joshua Guild, Mert Yuksekgonul, Eric Wu, James Zou. Preprint (SSRN).
2023
- Collecting Data When Missingness Is Unknown: A Method for Improving Model Performance Given Under-Reporting in Patient Populations
Kevin Wu, Dominik Dahlem, Christopher Hane, Eran Halperin, James Zou. CHIL 2023. - Analyses of Canine Cancer Mutations and Treatment Outcomes Using Real-World Clinico-Genomics Data of 2119 Dogs
Kevin Wu*, Lucas Rodrigues*, Gerald Post, Garrett Harvey, Michelle White, Aubrey Miller, Lindsay Lambert, Benjamin Lewis, Christina Lopes, James Zou. npj Precision Oncology 2023.
2022
- Machine Learning Prediction of Clinical Trial Operational Efficiency
Kevin Wu, Eric Wu, Michael DAndrea, Nandini Chitale, Melody Lim, Marek Dabrowski, Klaudia Kantor, Hanoor Rangi, Ruishan Liu, Marius Garmhausen, Navdeep Pal, Chris Harbron, Shemra Rizzo, Ryan Copping, James Zou. The AAPS Journal 2022.
2021
- How Medical AI Devices Are Evaluated: Limitations and Recommendations from an Analysis of FDA Approvals
Eric Wu, Kevin Wu, Roxana Daneshjou, David Ouyang, Daniel E. Ho, James Zou. Nature Medicine 2021. - Robust Breast Cancer Detection in Mammography and Digital Breast Tomosynthesis Using an Annotation-Efficient Deep Learning Approach
William Lotter, Abdul Rahman Diab, Bryan Haslam, Jiye G. Kim, Giorgia Grisot, Eric Wu, Kevin Wu, et al. Nature Medicine 2021. - Explaining Medical AI Performance Disparities Across Sites with Confounder Shapley Value Analysis
Eric Wu, Kevin Wu, James Zou. ML4H 2021.
2020 and earlier
- Synthesizing Lesions Using Contextual GANs Improves Breast Cancer Classification on Mammograms
Eric Wu, Kevin Wu, William Lotter. Preprint, 2020. - Validation of a Deep Learning Mammography Model in a Population with Low Screening Rates
Kevin Wu, Eric Wu, Y. Wu, H. Tan, G. Sorensen, M. Wang, William Lotter. NeurIPS 2019 Fair ML for Health Workshop. - Conditional Infilling GANs for Data Augmentation in Mammogram Classification
Eric Wu, Kevin Wu, David Cox, William Lotter. MICCAI 2018 Workshop. - Learning Scene Gist with Convolutional Neural Networks to Improve Object Recognition
Kevin Wu, Eric Wu, Gabriel Kreiman. CISS 2018. - Finding, Monitoring, and Checking Claims Computationally Based on Structured Data
B. Walenz, Y. Wu, S. Song, E. Sonmez, Eric Wu, Kevin Wu, P. K. Agarwal, J. Yang, et al. Computation+Journalism Symposium 2014.
Talks & Presentations
- Aug 5, 2024: Summer 2024. Invited talk: Towards Reliable, Valid, and Safe Systems for Biomedical Data Science, JSM 2024, Portland, OR.
- Dec 4, 2023: AI & Health Regulatory Policy Conference (Panelist)
- June 23, 2023: Conference on Health, Inference, and Learning (Oral Presentation)
- Apr 4, 2022: American Association for Cancer Research, Emerging Topics in Computational Oncology (Oral Presentation)